01
New projects
A paragraph about the problem is enough to start. We reply within two working days, usually with questions rather than a quote.
Data pipelines, a warehouse and dashboards people trust: tested transformations, agreed metric definitions, data quality alerts and clean inputs for AI.
Data engineering moves data from the systems where it is created to a place where it can be trusted and used. We build pipelines, a warehouse and the reporting on top, with tests on every transformation and one agreed definition for each metric — which is also the groundwork any AI or machine-learning project needs.
Scheduled and streaming ingestion from your databases, SaaS tools and files, with retries, backfills and a record of every run.
A warehouse with documented, version-controlled models, so each table says what it means and where it came from.
Checks for freshness, completeness and broken assumptions that alert the team before a wrong number reaches a meeting.
One written definition per metric, and dashboards built on those definitions instead of each analyst's own query.
Feature tables and training data with known lineage, and forecasting or classification models where the data supports them.
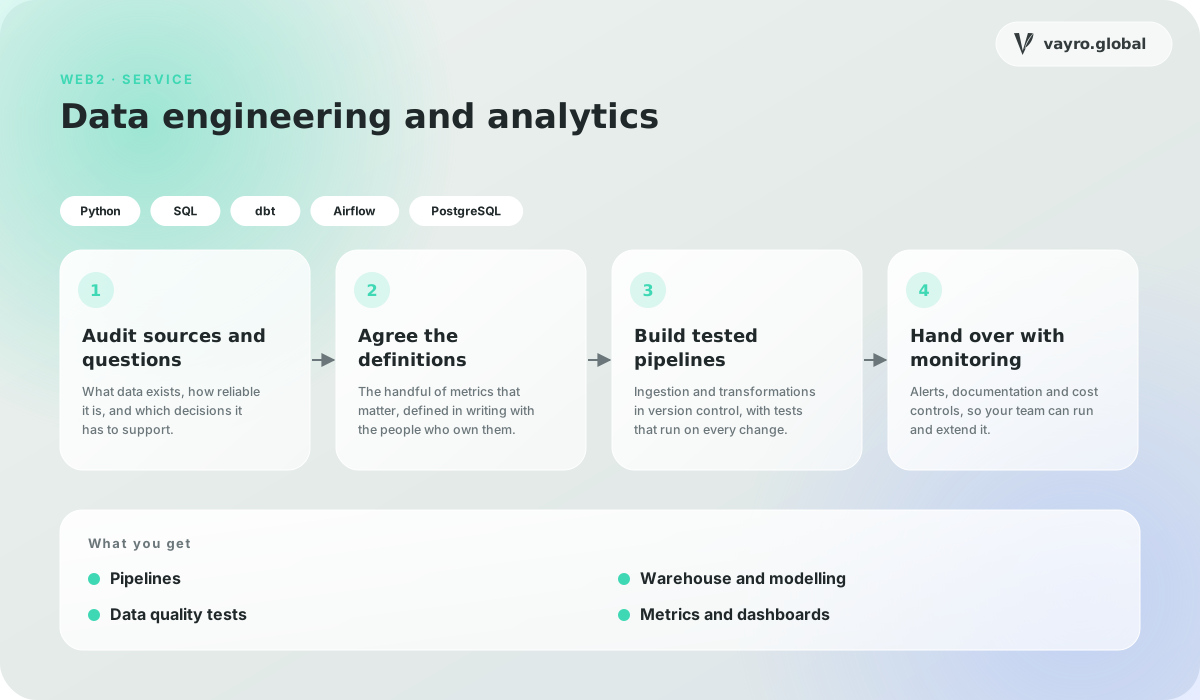
What data exists, how reliable it is, and which decisions it has to support.
The handful of metrics that matter, defined in writing with the people who own them.
Ingestion and transformations in version control, with tests that run on every change.
Alerts, documentation and cost controls, so your team can run and extend it.
A paragraph about the problem is enough to start. We reply within two working days, usually with questions rather than a quote.
Engineers, designers and researchers who like systems that are hard to get right. Send something you built and what you would change about it now.
Based in India and working remotely, with overlap hours agreed up front so your team always has a time to reach us.
Guides on AI agents, RAG, MCP, tokenization and chain abstraction, written by the engineers who build them.