01
New projects
A paragraph about the problem is enough to start. We reply within two working days, usually with questions rather than a quote.
Fine-tune language models when prompting and RAG fall short: data preparation, training on open or hosted models, evaluation and deployment.
Fine-tuning trains an existing language model further on your own examples, so it learns a format, style, classification or specialised task more reliably than instructions alone can achieve. It is not the usual way to give a model your knowledge — retrieval (RAG) does that better. We fine-tune when there is evidence it will beat a well-prompted model, and we prove it with evaluation.
A comparison of prompting, RAG and fine-tuning on your task before any training.
Collecting, cleaning, de-duplicating and labelling examples, with personal data removed.
Parameter-efficient fine-tuning such as LoRA on open models, or provider fine-tuning on hosted models.
The tuned model tested against the base model and the prompted baseline on held-out data.
Serving in your cloud or through a provider, with monitoring and a rollback to the base model.
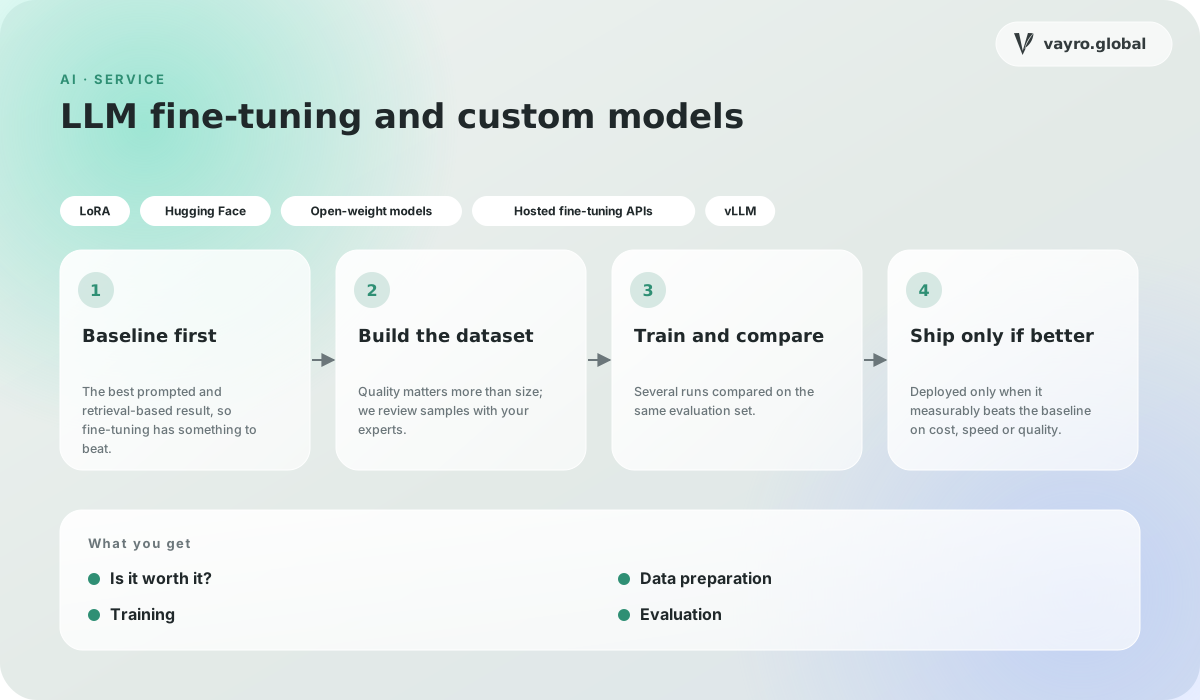
The best prompted and retrieval-based result, so fine-tuning has something to beat.
Quality matters more than size; we review samples with your experts.
Several runs compared on the same evaluation set.
Deployed only when it measurably beats the baseline on cost, speed or quality.
A paragraph about the problem is enough to start. We reply within two working days, usually with questions rather than a quote.
Engineers, designers and researchers who like systems that are hard to get right. Send something you built and what you would change about it now.
Based in India and working remotely, with overlap hours agreed up front so your team always has a time to reach us.
Guides on AI agents, RAG, MCP, tokenization and chain abstraction, written by the engineers who build them.